Spatial Cues Enhanced Multi-Channel Band-Split RNN for Regional Sound Extraction

Shengjie Lu1, Xiang Zhou1, Yichen Yang1, Bing Zhu1, and Wen Zhang1
1Center of Intelligent Acoustics and Immersive Communications, School of Artificial Intelligence, Northwestern Polytechnical University, Xi'an, Shaanxi, China

overview

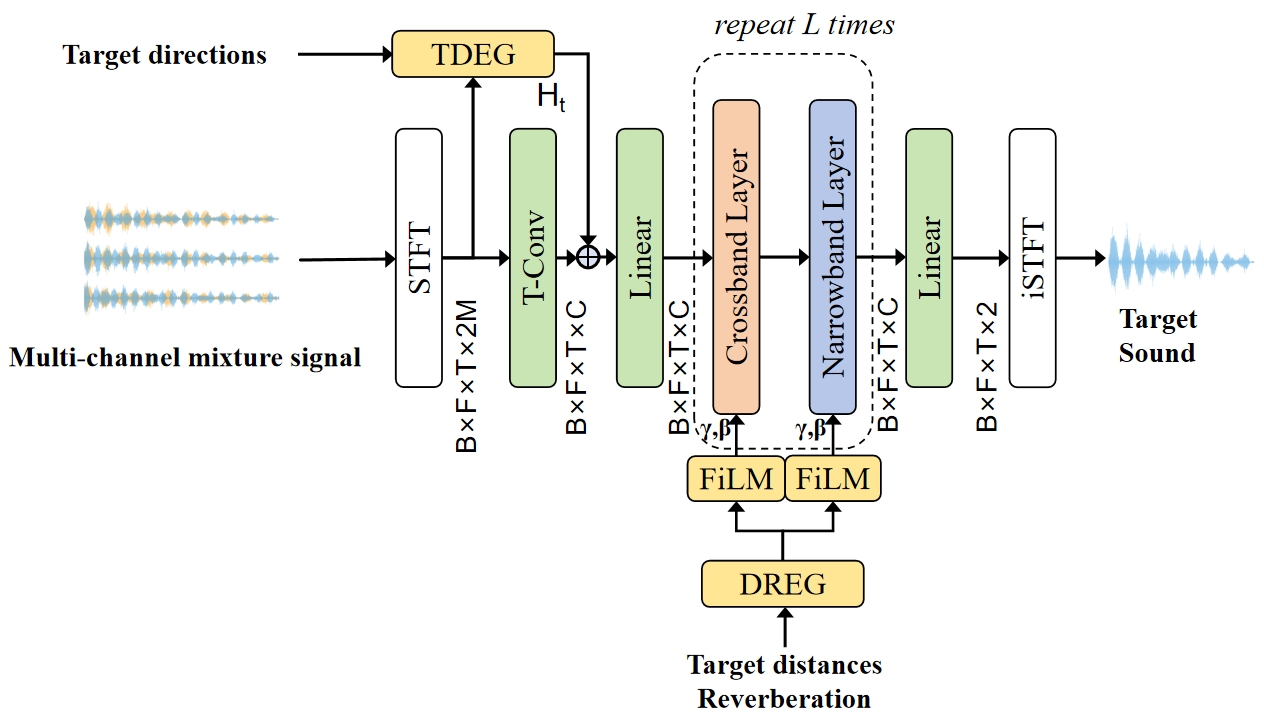
Abstract: Target speaker extraction (TSE) aims to isolate a desired talker from mixtures, but performance often collapses when an interferer is close to the target direction and when reverberation blurs spatial cues. We propose a spatially informed TSE framework built on the SpatialNet separation backbone and explicitly conditioned on direction, distance, and room acoustics. To improve angular discriminability, we introduce a high-resolution DOA embedding module that performs direction-aware convolution over a target angular region. To resolve spatial ambiguity when DOA cues are insufficient, we encode the target distance with a Gaussian-kernel soft representation rather than injecting a raw scalar. In addition, we provide explicit reverberation guidance using global room acoustic metrics and fuse these cues through Feature-wise Linear Modulation within the backbone. Experiments show consistent gains over recent DOA- and distance-conditioned baselines, and yield large improvements in extreme cases where target and interferer are nearly co-located in azimuth.


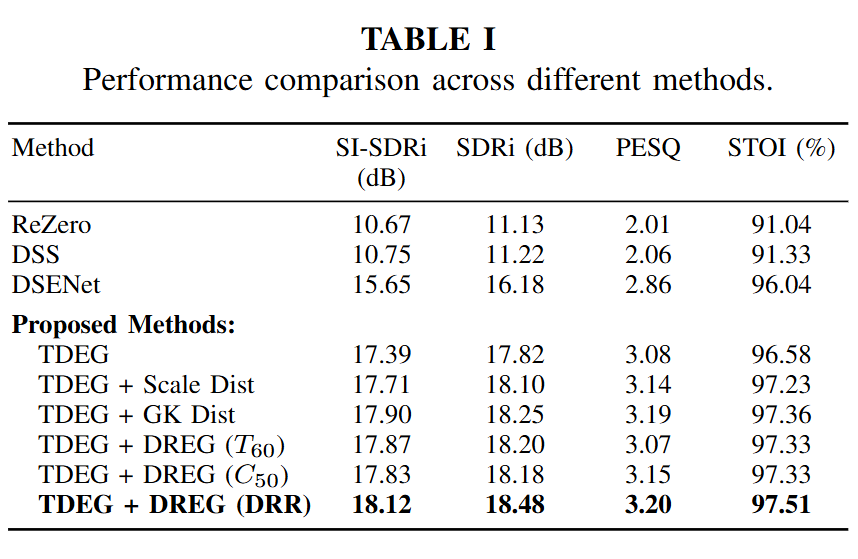
The separation performance on the Spatialized WSJ0-2mix and RealMAN datasets (click to expand)


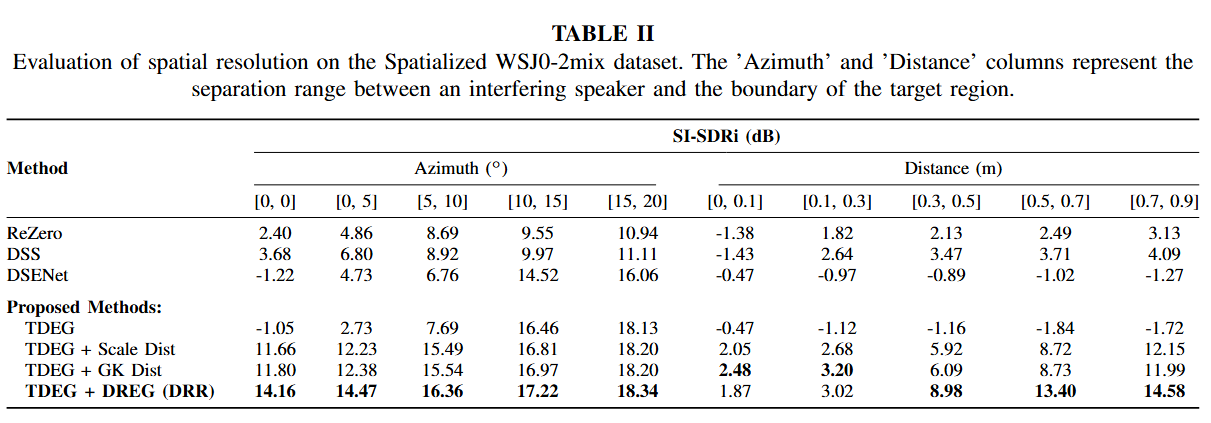
Evaluation of spatial resolution on the Spatialized WSJ0-2mix dataset (click to expand)


Audio samples (performance on two datasets)
Sample Mixture Target ReZero DSS DSENet Ours(TDEG) Ours(TDEG+scale dist) Ours(TDEG+GK dist) Ours(TDEG+DREG(DRR))
1

——

——

SI-SDR: 11.13dB

SI-SDR: 11.35dB

SI-SDR: 16.92dB

SI-SDR: 19.49dB

SI-SDR: 19.24dB

SI-SDR: 19.63dB

SI-SDR: 19.74dB

1

——

——

SI-SDR: 7.49dB

SI-SDR: 9.64dB

SI-SDR: 13.32dB

SI-SDR: 15.20dB

SI-SDR: 15.46dB

SI-SDR: 15.57dB

SI-SDR: 15.79dB

1

——

——

SI-SDR: 13.57dB

SI-SDR: 13.65dB

SI-SDR: 18.85dB

SI-SDR: 20.24dB

SI-SDR: 20.14dB

SI-SDR: 20.32dB

SI-SDR: 20.39dB

1

——

——

SI-SDR: 6.21dB

SI-SDR: 6.06dB

SI-SDR: 11.56dB

SI-SDR: 13.06dB

SI-SDR: 13.29dB

SI-SDR: 13.39dB

SI-SDR: 13.65dB

1

——

——

SI-SDR: 7.66dB

SI-SDR: 9.38dB

SI-SDR: 13.09dB

SI-SDR: 15.24dB

SI-SDR: 16.29dB

SI-SDR: 15.93dB

SI-SDR: 16.45dB

Audio samples (azimuth resolution capabilities)
Sample Mixture Target ReZero DSS DSENet Ours(TDEG) Ours(TDEG+scale dist) Ours(TDEG+GK dist) Ours(TDEG+DREG(DRR))
[0°,0°]

——

——

SI-SDR: -18.22dB

SI-SDR: -25.61dB

SI-SDR: -14.86dB

SI-SDR: -41.66dB

SI-SDR: 17.01dB

SI-SDR: 16.95dB

SI-SDR: 17.49dB

[0°,5°]

——

——

SI-SDR: 5.17dB

SI-SDR: 8.66dB

SI-SDR: 0.18dB

SI-SDR: -6.79dB

SI-SDR: 17.69dB

SI-SDR: 17.60dB

SI-SDR: 17.92dB

[5°,10°]

——

——

SI-SDR: 8.77dB

SI-SDR: 9.57dB

SI-SDR: 12.42dB

SI-SDR: 13.98dB

SI-SDR: 15.44dB

SI-SDR: 15.34dB

SI-SDR: 15.98dB

[10°,15°]

——

——

SI-SDR: 8.71dB

SI-SDR: 10.71dB

SI-SDR: 15.62dB

SI-SDR: 17.85dB

SI-SDR: 17.81dB

SI-SDR: 18.01dB

SI-SDR: 18.39dB

[15°,20°]

——

——

SI-SDR: 14.54dB

SI-SDR: 13.04dB

SI-SDR: 19.19dB

SI-SDR: 20.23dB

SI-SDR: 20.14dB

SI-SDR: 20.43dB

SI-SDR: 20.48dB

Audio samples (distance resolution capabilities)
Sample Mixture Target ReZero DSS DSENet Ours(TDEG) Ours(TDEG+scale dist) Ours(TDEG+GK dist) Ours(TDEG+DREG(DRR))
[0m,0.1m]

——

——

SI-SDR: -6.22dB

SI-SDR: -12.83dB

SI-SDR: -8.21dB

SI-SDR: -34.83dB

SI-SDR: -11.58dB

SI-SDR: -18.73dB

SI-SDR: -20.51dB

[0.1m,0.3m]

——

——

SI-SDR: -3.40dB

SI-SDR: 7.94dB

SI-SDR: -2.29dB

SI-SDR: -5.04dB

SI-SDR: 6.96dB

SI-SDR: 11.01dB

SI-SDR: 14.71dB

[0.3m,0.5m]

——

——

SI-SDR: 4.59dB

SI-SDR: 8.64dB

SI-SDR: 4.64dB

SI-SDR: 3.87dB

SI-SDR: 13.02dB

SI-SDR: 11.37dB

SI-SDR: 15.87dB

[0.5m,0.7m]

——

——

SI-SDR: -1.65dB

SI-SDR: -1.16dB

SI-SDR: -13.28dB

SI-SDR: -11.83dB

SI-SDR: -24.82dB

SI-SDR: 13.41dB

SI-SDR: 15.48dB

[0.7m,0.9m]

——

——

SI-SDR: 2.90dB

SI-SDR: 3.46dB

SI-SDR: 3.09dB

SI-SDR: -8.91dB

SI-SDR: -12.01dB

SI-SDR: 14.90dB

SI-SDR: 15.77dB